Introduction to Large Language Models
Handling Long Sequences, Computational Complexity of Transformers, Fast Attention Mechanisms
Mitesh M. Khapra, Arun Prakash A

AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Motivation
The models that we have discussed so far have a limited context length of 512 or 1024(GPT-2)
What about other sequences like audio and images (viewing pixels as sequences)?
The sequence length of an audio signal of 10s duration is about 80000 (assuming sampling rate of 8000 Hz)
The sequence length of a colour image of size 100 by 100 is 30000.
So, enabling the models to attend to longer sequences is crucial.
What if we want to summarize a book that contains, say 64000 words?
What if we want to generate a story that contains at least 5000 words?
What if we want to find an answer to a question from an instruction manual that contains a thousand pages?
Motivation
The context lengths of some of the recent models are listed below
| Model | Context length |
|---|---|
| LLAMA-2 | 4K |
| Mistral-7B | 8K |
| GPT-4, Gemini 1.0 | 32K |
| Mosaic ML MPT | 65K |
| Anthropic Claude | 100K |
| Gemini 1.5 pro, GPT-4 Turbo | 128K |
| Claude 2.1 | 200K |
| Gemini 1.5 pro (limited) | 2 million (for public) 10 million (experimental) |
Why is it difficult to scale the context length?
One of the primary factors is the computational complexity of the self-attention mechanism.
Let us first try to understand the computational complexity and memory requirements to train Transformer based models.
Module 1: Time and Space Complexity of Attention Mechanism
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Mitesh M. Khapra, Arun Prakash A
Attention Mechanism
Context window size: \(T\)
The size of the (projected) embeddings: \(d = d_q=d_k\)
Attention Mechanism
Context window size: \(T\)
The size of the (projected) embeddings: \(d = d_q=d_k\)
One dot product between \(d_q \cdot d_k^T\) requires \(d\) multiplications and \(d-1\) additions
Attention Mechanism
Context window size: \(T\)
The size of the (projected) embeddings: \(d = d_q=d_k\)
Number of operations for computing one row of unnormalized attention weights \(Z \in \mathbb{R}^{T \times T}\) is..
\(T \cdot d\) multiplications and \(T \cdot (d-1)\) additions
Attention Mechanism
Context window size: \(T\)
The size of the (projected) embeddings: \(d = d_q=d_k\)
Number of operations for computing one row of unnormalized attention weights \(Z \in \mathbb{R}^{T \times T}\) is:
\(T \cdot d\) multiplications and \(T \cdot (d-1)\) additions
The number of tokens \(T\) is typically greater than embedding dimension \(d\).
Therefore, to compute \(QK^T\) we require \(\mathcal{O}(T^2d)\) operations
What about computing attention score by normalizing the unnormalized matrix \(Z\) ?
Attention Mechanism
There are \(T\) rows in \(Z\), therefore computational complexity for \(softmax\) is \(\mathcal{O}(T^2)\).
\(\therefore\) The computational complexity of \(A\) is \(\mathcal{O}(T^2d)\).
We need to normalize each row of \(Z\), this requires \(O(T)\) operations.
Attention Mechanism
Finally, the attention score matrix \(A\) is multiplied with the value matrix \(V\)
Attention Mechanism
Therefore, the entire self-attention block is quadratic \(\mathcal{O}(T^2d)\) in the length of the input sequence.
Finally, the attention score matrix \(A\) is multiplied with the value matrix \(V\)
This has a complexity of \(O(T^2 d)\)
Module 2: Memory Requirements
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Mitesh M. Khapra, Arun Prakash A
Notations
\(B\): Batch Size

\(T\) : Context (sequence) Length
\(n_h\) : Number of attention heads
\(d_{model}\) : Dimension of input embedding, \(d_{att}=512=\frac{d_{ff}}{4}\)
\(N\) : Number of parameters in the model
\(|\mathcal{V}|\) : Number of tokens in the vocabulary
\(d_{ff}\) : Dimension of feed-forward layer
Memory for Attention
Memory scales up linearly with respect to batch size \(B\) and quadratically with respect to the length of the context window \(T\).
For a single sample
For a batch of \(B\) samples
Key Take Aways
The complexity of Self-attention is quadratic in the length of the input sequence.
Memory scales up linearly with respect to batch size \(B\) and quadratically with respect to the length of the context window \(T\).
So, the next question is, How do we reduce the time complexity to enable models to handle long sequences (during both training and inference)?
Module 3: Fast Attention Mechanisms
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Mitesh M. Khapra, Arun Prakash A
What we have is the full attention mechanism with \(O(T^2d)\) complexity. What we want is sub-quadratic complexity \(O(cTd)\). How do we achieve that?
Objective
Well, we can localize the attention in multiple ways.
This gives rise to a plethora of approaches that approximate the full attention.
A study on BERT [Ref] in NLP tasks concluded that the neighbouring inner products are extremely important in self-attention and not all heads attend to all tokens.

Approaches
Strided Local Attention
Strided Local Attention
Approaches
Random Local Attention
Sparse Block Attention
Strided Local Attention
Approaches
Random Local Attention
Sparse Block Attention
Strided Local Attention
Global+local attention
Approaches
Random Local Attention
Sparse Block Attention
Strided Local Attention
Global+local attention
Random Local Attention
Approaches
Flash Attention
Our planet is a lonely speck
Full Attention
Every word attends to every other word in the input sequence
Our planet is a lonely speck
Our planet is a lonely speck
Computational complexity \(O(T^2d)\)
How do we reduce the computational complexity?
Our focus is on reducing the computational complexity.
Memory complexity \(O(T^2)\)
One way is to make it sparse by attending to a subset of words instead of all words
(the score for the word itself (\(q_ik_i^T\)))
\(O(c \times T \times d)\) where \(c < T\)
Our planet is a lonely speck
Strided Local Attention
Our planet is a lonely speck
Our planet is a lonely speck
Linear Computational complexity \(O(cTd)\)
\(c=3\)
Every word attends to a window of \(c\) words (\(\lfloor \frac{c}{2} \rfloor\) to the left and \(\lfloor \frac{c}{2} \rfloor\) words to the right)
We could vary the size of the window for each layer in the model such that the top most layer uses the full (global) attention
Strided Local Attention
\(O(3Td)\)
\(c=3\)
\(c=5\)
\(O(5Td)\)
Our planet is a lonely speck
Our planet is a lonely speck
Our planet is a lonely speck
Every word attends to a window of \(c\) words (\(\lfloor \frac{c}{2} \rfloor\) to the left and \(\lfloor \frac{c}{2} \rfloor\) words to the right)
Our planet is a lonely speck
Our planet is a lonely speck
Our planet is a lonely speck
We could also use dilated attention (like dilated convolutions) by using different dilation rates in different attention heads.
Dilated Attention
\(O(3Td)\)
\(c=3\)
Note that, there is no change in computational complexity.
Every word attends to a window of \(c\) words (\(\lfloor \frac{c}{2} \rfloor\) to the left and \(\lfloor \frac{c}{2} \rfloor\) words to the right)
Tokens like [cls] requires full attention to get good performance in downstream tasks.
Global + local Attention
\(O((3T+T)d)\)
\(c=3\)
[cls] Our planet is a lonely speck
We can manually set tokens that require global attention based on the task.
A few words are global, every other word attends to a window of \(c\) words (\(\lfloor \frac{c}{2} \rfloor\) to the left and \(\lfloor \frac{c}{2} \rfloor\) words to the right).
Our planet is a lonely speck
Our planet is a lonely speck
Our planet is a lonely speck
Tokens like [cls] requires full attention to get a good performance in downstream tasks.
Global + Random+ local Attention
\(O((3T+T+T)d)\)
\(c=3\)
[cls] Our planet is a lonely speck
The BIGBIRD model proposes adding random tokens.
A few words are global, every other word attends to a window of \(c\) words (\(\lfloor \frac{c}{2} \rfloor\) to the left and \(\lfloor \frac{c}{2} \rfloor\) words to the right).
Our planet is a lonely speck
Our planet is a lonely speck
Our planet is a lonely speck
Our planet is a lonely speck
Local Block Attention
Another way is to divide the sequence into \(n\) blocks and do the computations independently as in [Ref]
Computational complexity \(O(\frac{T^2}{2})\)
Typically, \(n=2,3,4\). Therefore, for a context length of 512, the block sizes will be 256, 128, 64.
These are resonable context sizes for majority of NLP tasks.
MHA
MHA
Merge
We could also use different patterns in each attention head/layer.
Suppose we have \(n=4\) blocks. Then we can permute these blocks in 16 possible ways (how? will see soon)
Therefore, we can permute these blocks in each attention head so that it could effectively capture long range dependencies.
Full Attention
Let's recall how we compute the attention matrix
Full Attention
Let's recall how we compute the attention matrix.
We can divide \(Q\) and \(K\) matrices into \(n\) blocks each. This will result in \(n^2\) blocks in \(QK^T\) as shown in the figure above.
Block Attention
Let's recall how we compute the attention matrix.
We can divide \(Q\) and \(K\) matrices into \(n\) blocks each. This will result in \(n^2\) blocks in \(QK^T\) as shown in the figure above.
Suppose we want to select only 3 blocks.
There are many ways of selecting 3 blocks from the set of \(B=9\) blocks. Let's formalize this.
Suppose we want to select only 3 blocks.
Let's recall how we compute the attention matrix
We can divide the each \(Q\) and \(K\) matrices into \(n\) blocks, this will result in \(n^2\) blocks in \(QK^T\) as shown in the figure above
Block Attention
Block Attention

Block Attention is given by,
For example, suppose context length \(T=15\) and the number of blocks \(n=3\).
Write \(Q\),\(K^T\), and \(V\) into \(n=3\) block matrices (following the blocks in \(M\))
Then we would have 3! ways of permuting the blocks.
Consider the permutation,
\(\pi=\text{perm}(0,1,2,\cdots, n-1)\)
Let the \(k\)-th element of \(\pi\) be \(\pi(k)\), We define the masking matrix \(M\) of size \(T \times T\)
Computational Complexity
Using these we can compute Block Attention as follows
We can extend the same concept to Multi-head attention by allowing each head to use a different masking matrix (derived from the permutation function).
This would be called Blockwise Multi-Head Attention.
What happens if we increase value of \(n\)?

50% non-zero values

6.25% non-zero values
(50% sparse)
(93% sparse)
Capturing Long Term dependency
Blockwise sparsity captures both local and long-distance dependencies in a memory-efficient way using different permutations

Empirically, it is observed that the identity permutation is more important than other permutations

Using blockwise sparse attention reduces the training time significantly for longer sequences.
Note, however, that the perplexity score increases as the number of blocks \(n\) increases.
This is reasonable given that local attention is just an approximation to full attention. (This is the case for all local attention schemes.)
Performance
Locality Sensitive Hashing [Paper]

Let us pick up two rows in the attention matrix show on the left
For the given query \(q_i\), we know that the attention score is higher for some of the keys \(k_j\)
Can we find those \(k_j\)'s without resorting to computing pair-wise dot product with all the keys?
It is similar to approximating attention using the K-Nearest Neighbours (KNN) search. For example, if K is of length 64K, for each \(q_i\) we could only consider a small subset of, say, the 32 or 64 closest keys
One of many possible ways of doing this is to use Locality Sensitive Hashing (LSH) (Yes, the same one we used for deduplication of contents!)
The attention matrix is mostly sparse !
However, there is a catch!
For this to work, we need \(Q=K\).This requires us to share the weight matrices \(W_Q=W_K\).
We look for a hashing scheme that assigns each vector \(x\) (query) to a hash bucket such that nearby vectors falls in the same hash bucket and distant ones do not. This is called locality-sensitive hashing
Let's see how we construct hash buckets using a hash function with a help of an example (in 2D case)


For each query, it takes \(log(T)\) time to find the approximate nearest neighbours [ref], therefore, its computational complexity is \(O(T \log(T))\)
Assume,
Consider a query (and a key) \((x=q_1,y=k_2)\) that are away from each other and first projected onto a sphere
Define the number of hash buckets, \((b=4)\)
Let the random rotation matrix \(R\) be of size \([d_k,b/2]\).
for illustration,
Let us define the hash function

\(hash(q_1)= \textit{argmax}(concat(0.5,0.25,-0.5,-0.25))=0\)
\(hash(k_2)= \textit{argmax}(concat(-0.25,-0.5,0.25,0.5))=3\)
\(hash(q_1)= \textit{argmax}(concat(0.5,0.25,-0.5,-0.25))=0\)
\(hash(k_2)= \textit{argmax}(concat(-0.25,-0.5,0.25,0.5))=3\)
Recompute the hash by changing the rotation matrix a few times


The probability that the given query and the key share the same bucket is \(\frac{1}{3}\). Therefore, they are not close to each other
Let's consider a query and a key that are close to each other
Recompute the hash by changing the rotation matrix few times
The probability that the queries share the same bucket is \(\frac{3}{3}\). Therefore, they are close to each other

Therefore, all the points that are close to each other would share the same bucket.
Essentially compute the hash for all the queries (repeat \(n_R\) times if required)
This can be computed in parallel by multiplying all the queries with the random matrix \(R\)
| Query | hash by R1 | hash by R2 |
|---|---|---|
| 0 | 2 | |
| 3 | 2 | |
| 0 | 2 | |
| 0 | 2 |
Now, sort the queries by bucket number,
Essentially compute the hash for all the queries (repeat \(n_R\) times if required)
This can be computed in parallel by multiplying all the queries with the random matrix \(R\)
| Query | hash by R1 | hash by R2 |
|---|---|---|
| 0 | 2 | |
| 0 | 2 | |
| 0 | 2 | |
| 3 | 2 |
Now, sort the queries by bucket number,
Compute the attention scores for queries within each bucket. For example, in ClM, \(q_3 \) attends to \(q_1\), and \(q_{16}\) attends to \(q_3\) and \(q_{1}\) and so on
and within each bucket, by sequence position
The entire procedure is captured in the figure below

The entire procedure is captured in the figure below
The entire procedure is captured in the figure below
The entire procedure is captured in the figure below
The entire procedure is captured in the figure below
Self-attention is Low rank [paper]
The methods that we have seen so far localize or sparsify the attention matrix in different ways
The theoretical time complexity is sub-quadratic \(O(cTd)\), with \(c\) being a constant (manually set, or function of \(T\) such as \(log(T)\))
Can we reduce it to \(O(Td)\)? Yes, as follows :-)
Well, this is not helpful to capture the context.
However, we can see from empirical observation that the self-attention matrix is essentially low-rank (especially for the top layers)!
Apply SVD on the matrix \(A\) across different layers and different heads of the model, and plot the normalized cumulative singular value averaged over 10k sentences.
Consider a RoBERTa model trained on Wiki-103 (MLM task) and a classification task.
Suppose we plot the distribution of all 512 singular values . Then, for it to be a low-rank it should follow a ____ distribution.
They observed a long tail distribution. Hence they concluded the matrix A is a low-rank matrix.

Using this observation, they show that there exists a low-rank approximation of \(QK^T\) and we can let the network to find (learn) it! How?
Introduce two learnable linear projection matrices

The computational complexity is \(O(kTd)\), where \(k\) is the rank and can be set according to the error \(\epsilon\)
Kernel Methods [paper]
All that we need is an attention matrix such that each row sums up to one
Fundamentally, the exponential function in \(A\) takes in the query and key vectors and outputs a positive number.
where,
\(\mathbf{1}\) is a vector of all ones of length \(T\)
So we can generalize this
\(\mathcal{K}\) is called a Kernel function, and defined as follows
Where \(\phi(x)\) is some randomized feature mapping and \(\mathbb{E}\) is an expectation operator.
Note that \(r>0\), and it is not necessary that \(r <d\).
For example, \(T=64k,d=4k\), then \(r=8k\) is also reasonable
How do we compute \(\phi(x)\)?
The generalized form of a kernel transformation is given by,
where \(w_i\) is sampled from \(\mathcal{N}(\mathbf{0}_d,\mathbf{ I}_d)\)
\(w_i^Tx\) is a random projection, that is, the vector \(x\) is projected in a random direction given by \(w_i\) vector.
We can construct a random feature vector of size \(r\) by setting \(l=1\), considering \(f_1=exp\) and \(h(x)=exp(\frac{-||x||^2}{2})\) (Note, this particular setting is theoretically motivated among many possible choices.)
where,
Therefore,
where \(\mathbf{W} \in \mathbb{R}^{d \times r}\) ,\(X \in \mathbb{R}^{d \times T}\) and \(||X||^2\) is the \(L2-\)norm of column vectors in \(X\).
\(w_i \sim \mathcal{N}(\mathbf{0}_d,\mathbf{ I}_d)\)
We can collect all \(w_i\)s in a matrix \(\mathbf{W}\)
For all the queries \(q_i\)s in \(Q\), we can compute \(Q'\) as follows
here, \(\mathbf{W} \in \mathbb{R}^{r \times d}\) ,\(Q \in \mathbb{R}^{T \times d}\) and \(||Q||^2\) is the \(L2-\)norm of row vectors in \(Q\).
Similary, we can compute \(K' \in \mathbf{R}^{T \times r}\).
The \(\mathbf{W}\) matrix is orthogonalized using Gram-Schmidt orthogonalization procedure.
Orthogonalization of W helps reduce the variance of the softmax estimator for any dimensionality of \(d\). This requires \( r \leq d\).


The time complexity is \(O(rTd)\).
The approximated attention matrix for the given query and key is given by
and the vectorized version is given by
\(L=T\) in the figure below
All these approaches that we have discussed so far approximated the full attention.
Reduced FLOPS != Reduced Wall clock speed
However, it does not translate to wall-clock speed-up!
That is, suppose we train a model with the compute requirement \(C \propto T^2\) FLOPS for a day.
Reducing the compute requirement \(C \propto \frac{T^2}{2}\) FLOPS will not reduce the training time to half a day
So, the problem is not in the algorithm but..
Module 4: Know your hardware to get wall-clock speed
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Mitesh M. Khapra, Arun Prakash A
Flash Attention: Exact Attention with IO Awarness
All Transformer based language models are trained on GPUs.
However, it was observed that the implementation of MHA did not efficiently utilize GPUs.
In fact, the training time is now memory bound not compute bound!
Let us try to understand this with a help of a simple example.
What are the sequence of steps involved in computing any mathematical operation? For example, consider a product of two numbers and computing square root of the result
Main Memory (DRAM)
Compute
(Registers)
Read (a,b, and mul instruction)
write (c)
Main Memory (DRAM)
Compute
(Registers)
Read (c, and sqrt instruction)
write (d)
Therefore, there are two read operations, two write operations and two compute operations. The compute was not utilized during writing the result back to memory!
Typically, after executing an operation, the result is written back to main memory.
How do we skip this redundant reading from/ writing to memory as we are aware that the result \(c\) will be used in the subsequent operation?
compute is idle
Kernel fusion
We can fuse the sequence of operation (called kernel fusion) as follows \(c=\sqrt{ab}\)
Main Memory (DRAM)
Compute
(Registers)
Read (a,b, mul,sqrt)
write (c)
We can store the intermediate result of the multiply operation in the registers/cache memory and take square root on it, then write the final result back to main memory
Therefore, Kernel fusion helps optimally utilize the compute capacity by making it aware that the intermediate results need not be written back to main memory!
Let us see the amount of time spent by the naive implementation of MHA and MHA using Kernel fusion.
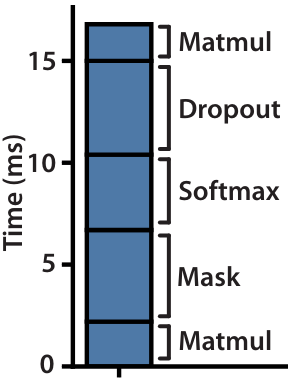
Naive implementation
Do you see anything surprising from the diagram?
Dropout, softmax, and masking take more time to execute than MatMul!
In general, all element-wise operations like activation, normalization are all memory bound
A general approach to alleviate this problem is to use kernel fusion!
We write the output back to memory at every step and read the previous output as an input for the next step!
Naive implementation
At every step, we write an output back to memory and read the previous output as an input for the next step!

There is a catch! We need to store \(QK^T\) for backward pass!
Getting into Details

Standard attention is memory bound.
Objective: Given \(Q,K,V\), compute \(O\) and write it to HBM (High Bandwidth Memory) (Note: using only one write operation).
We can not use entire Q, K, and V matrices. We need to divide each of these into blocks. Why?

Memory Hierarchy
High Bandwidth Memory (the one you get when you type nvidia-smi command) is the place where we load and store data, model parameters, and all intermediate results.
SRAM has small memory (20MB) (distributed across cores each of size about 100KB) with a high bandwidth (19TB/s)
Suppose we have a sequence of length 1024, to store \(Q,K\) using 4 bytes (32 bit) per element requires \(2 \times 1024 \times 64 \times 4 = 524 KB \).
So, it is not possible to fit in the entire Q and K matrices into SRAM.
IDEA
1. Tiling: Divide the matrices \(Q,K,V\) into small blocks (in HBM) such that it fits into the SRAM of size \(M\) (around 100 KB) and compute attention by blocks
We apply the softmax function for each block of \(Q_iK_j^T\).
However, we have only \(S_{ij}\) but the softmax requires all the elements in \(S\) for normalization
How do we go from \(S_{ij}\)'s to \(P\)?
IDEA
1. Divide the matrices \(Q, K,\) and \(V\) into small blocks (in HBM) such that it fits into the SRAM of size \(M\) (around 100 KB)
\(P=ConCat(\beta_0f_{00},\beta_1f_{01},\cdots, \beta_8 f_{22}\))
How do we compute the weight \(\beta_i\) for each block ?
\(f_{ij}\) is an intermediate sequence
IDEA
How do we compute \(\beta_i\)?
Let us take a simple example to illustrate the idea
Before going further, we use a variation of softmax implementation called "Safe softmax" in which we subtract the maximum of the vector from all its elements because the exponential operator is more accurate for negative inputs [Ref]
where,
\(x=[x^A,x^B]\) where,\(x^A\): -1.02 -1.09 0.24 0.87 -1.32, \(x^B\): -0.6 -5.04 -2. 1.03 -0.14
Consider an example sequence \(x\) divided into two consecutive sub-sequences \(x^A\) and \(x^B\).
Online softmax
How do we compute \(\beta_i\)?
Let us take a simple example to illustrate the idea
\(x^A\): -1.02 -1.09 0.24 0.87 -1.32 \(x^B\): -0.6 -5.04 -2. 1.03 -0.14
\(m_1=max(x^A)\)
0.15 0.14 0.53 1. 0.11
\(m_2=max(x^B)\)
0.2 0. 0.05 1. 0.31
Combine
Split
\(m=max(m_1,m_2))\)
0.13 0.12 0.45 0.85 0.1 0.2 0. 0.05 1. 0.31
0.04 0.04 0.14 0.27 0.03 0.06 0. 0.01 0.31 0.1
We need to keep track of \(m_i\)'s and \(l_i\)'s to get \(P\) from \(f_i\)'s
IDEA
1. Divide the matrices \(Q,K,V\) into small blocks (in HBM) such that it fits into the SRAM of size \(M\) (around 100 KB)
Subsequently, we apply the softmax function over each blocks of \(Q_iK_j^T\).
However, recall that softmax requires all the elements in \(S\)
How do we go from \(S_{ij}\)'s to \(P\)?
Algorithm
1. Get \(Q,K,V\) (in HBM) and size of SRAM \(M\) (around 100 KB)
2. Determine the block sizes \(B_c=\lceil \frac{M}{4d} \rceil\), \(B_r=min((\frac{M}{4d},d)) \)
For, \(d=64\) and assigning 4 bytes per element, the \(B_c=\frac{100 \times 1024 \ B}{4 \times 64 \times 4 \ B} = 100, B_r=64 \)
3. Initialize \(O \in \mathbb{R}^{N \times d}\) , \(l \in \mathbb{R}^N\),to zeros and \(m \in \mathbb{R}^N\) to \(-\infty\), (in HBM)
4. Divide \(Q\) into \(T_r=\lceil\frac{N}{B_r}\rceil\) blocks and \(K,V\) into \(T_c=\lceil\frac{N}{B_c}\rceil\) blocks
Algorithm
1. Get \(Q,K,V\) (in HBM) and size of SRAM \(M\) (around 100 KB)
2. Determine the block sizes \(B_c=\lceil \frac{M}{4d} \rceil\), \(B_r=min((\frac{M}{4d},d)) \)
For, \(d=64\) and assigning 4 bytes per element, the \(B_c=\frac{100 \times 1024 \ B}{4 \times 64 \times 4 \ B} = 100, B_r=64 \)
3. Initialize \(O \in \mathbb{R}^{N \times d}\) , \(l \in \mathbb{R}^N\),to zeros and \(m \in \mathbb{R}^N\) to \(-\infty\), (in HBM)
4. Divide \(Q\) into \(T_r=\lceil\frac{N}{B_r}\rceil\) blocks and \(K,V\) into \(T_c=\lceil\frac{N}{B_c}\rceil\) blocks
5. Divide \(O\) into \(T_r\) blocks, and \(l,m\) into \(T_r\) segments of size \(B_r\)
Let us visualize the subsequent steps

Suppose \(N=128, d=16,B_c=16,B_r=32\)
A zero vector
Suppose \(N=128, d=16,B_c=16,B_r=32\)
Suppose \(N=128, d=16,B_c=16,B_r=32\)
Suppose \(N=128, d=16,B_c=16,B_r=32\)
Suppose \(N=128, d=16,B_c=16,B_r=32\)
Now we have \(m_1,l_1\) computed from \(S_{11}\)
Next, increment the outer loop by 1 and compute \(m_2,l_2\) from \(S_{22}\)
Iteratively update \(O_i\)'s
in HBM
Suppose \(N=128, d=16,B_c=16,B_r=32\)
in HBM
in SRAM
Suppose \(N=128, d=16,B_c=16,B_r=32\)
in HBM
in SRAM
Suppose \(N=128, d=16,B_c=16,B_r=32\)
in HBM
in SRAM
Suppose \(N=128, d=16,B_c=16,B_r=32\)
in HBM
in SRAM
Suppose \(N=128, d=16,B_c=16,B_r=32\)
in HBM
in SRAM
Iteratively update the statistics and keep refining \(O_i\)
Suppose \(N=128, d=16,B_c=16,B_r=32\)
Final output representation from a single head
in HBM
HBM Access
Standard attention requires \(O(𝑁 𝑑 + 𝑁^2 )\) HBM accesses
FlashAttention requires \(O(\frac{𝑁^2𝑑^2}{M} )\) HBM accesses.
Recomputation
We need to store \(S=QK^T,P=softmax(S)\) for it to be used during backward propagation
However, kernel fusion does not store these intermediate quantities. Then how do we recover these?
We can recompute these quantities by using \(O\) and the statistics \(m,l\)

Did we achieve wall-clock speed up?
For the given compute budget, we can increase the context length from \(1K\) to \(4k\) using Flash Attention

There are many places where one could apply tiling and recomputation techniques to reduce the number of HBM accesses.
Hint: Not during training
Could you think of one more common use case scenario where the operation is memory-bound?
Model Inference with autoregressive generation
We can not directly use Flash Attention (by parallelizing across queries and batch) in inference as we do not even have the whole \(Q,K,V\) matrices. It is gradually built for each time step.
So, we need a different mechanism to reduce the number of accesses to memory
The methods for inference optimization by reducing memory access (CPU/GPU) were proposed years before the introduction of Flash Attention!
However, recently a modified Flash Attention (that parallelizes across keys/values and sequence length) was adapted for inference. Take a look at Flash Decoding.
Module 5: Fast Inference
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Mitesh M. Khapra, Arun Prakash A
Let's take a closer look at the naive implementation of autoregressive inference and see why it matters to optimize the inference pipeline
Embedding
Embedding
At each time step, we compute the keys-values for all the previous queries as well. This is a waste of compute and moreover increases the latency. Moreover, processing an LLM request can be 10x more expensive than a traditional keyword query. Can we do better?
Embedding
Embedding
Embedding
KV Caching
In the first time step, we start with a query, compute its key-value pair for the given input token when running the model in autoregressive mode.
Store the key value in cache (usually GPU RAM which has HBM) .
For the new query \(q_3\) in time step 3, we reload keys and values \(k_1,v_1,k_2,v_2\) from previous times steps from HBM and compute \(k_3,v_3\)
In this way, we trade off the memory for compute and the compute scales linearly \(O(n)\)
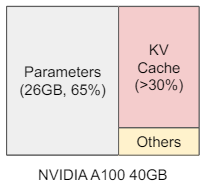
Since KV-caching uses GPU RAM where the model weights are stored, we cannot let the memory for KV-cache to grow indefinitely!
For the new query \(q_2\) in time step 2, we reload \(k_1,v_1\) from HBM and compute \(k_2,v_2\)
Let 's take an example.
KV cache per token (in B) =
2 \(\times\) num_layers \(\times\) (num_heads \(\times\) dim_head) \(\times\) precision_in_bytes
Model GPT-3
- num_layers = 96
- num_heads = 96
- dim_head = 128
- precision_in_bytes=4
KV cache per token = 2 \(\times\)96\(\times\) (96 \(\times\) 128) \(\times\) 4
= 9.4 MB
For 2K context length = 2048 \(\times\) 9.4 MB
= 19.3 GB
to generate a sequence of length 2K requires 19.3 GB of memory for KV caching alone (we can't even use an A100 40 GB GPU).
A practical solution is to drop the keys and values of tokens that occured in the distant past (act similar to local windowed attention).
The other approach is to introduce model level modifications!
Multi-Query Attention (MQA)
KV cache per token (in B) =
2 \(\times\) num_layers \(\times\) (num_heads \(\times\) dim_head) \(\times\) precision_in_bytes
Select one hyper-parameter out of three hyperparameters that we could exploit in the formula to reduce the memory requirement is ____
Let's set \(num\_heads=1\) (it does not imply we use only one head). The number 2 in the formula means that we access two vectors (key-value) for each head.
Therefore, it means we want to access key-value pairs once for all the heads!
How can we do that?
Share all the key-value pairs across the heads.
Cache Memory
This greatly reduces the cache memory. However, the performance degrades significantly.
Moreover, this requires us to re-train the model with at least 5% of training data
Grouped-Query Attention (GQA)
On one extreme we have Multi-Head Attention where each head has a separate query, key and value vector.
On the other extreme we have Multi-Query Attention where each head has separate query but keys and values are shared across all heads.
Grouped Query Attention is just a middle ground between the two, where a group of queries share key-value pairs that result in performance close to MHA

Paged Attention (PA)
Typically, fixed and contiguous memory is reserved for KV-caching (say, based on context length of the model).
However, we do not know the length of the sequence that the model generates a priori.
The memory during the generation process is wasted if the model generated a sequence that is much smaller than the pre-fixed length.
A solution is to use a block of non-contiguous memory locations.
That is what Paged Attention does

