CS6910: Fundamentals of Deep Learning
Lecture 5
Gradient Descent (GD), Momentum Based GD, Nesterov Accelerated GD, Stochastic GD, AdaGrad, AdaDelta, RMSProp, Adam (and its variants)
Mitesh M. Khapra, Arun Prakash A

AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Module 5.1: Learning Parameters :
Infeasible (Guess Work)
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
1
x
\sigma
f(x) = \frac{1}{1+e^{-(wx+b)}}
\hat{y}=f(x)
w
b
Input for Training
\(\{x_i,y_i\}_{i=1}^N \rightarrow N \ \text{pairs of} \ (x,y) \)
Training Objective
Find \( w\) and \(b \) such that
\( \underset{(w,b) \in R} {minimize}\) \( \mathscr{L(w,b)}= \frac{1}{N}\sum \limits_{i=1}^N (y_i-f(x_i))^2 \)
What does it mean to train the network?
Suppose we train the network with \( (x, y) = (0.5, 0.2) \) and \((2.5, 0.9)\)
x
y
(x_1,y_1)
(x_2,y_2)
f(x) = \frac{1}{1+e^{-(wx+b)}}
At the end of training we expect to find \(w^*\), \(b^*\) such that:
\( f(0.5) \rightarrow 0.2 \ \text{and} \ f(2.5) \rightarrow 0.9 \)
In other words
We hope to find a sigmoid function such that \((0.5, 0.2)\) and \((2.5, 0.9)\) lie on this sigmoid
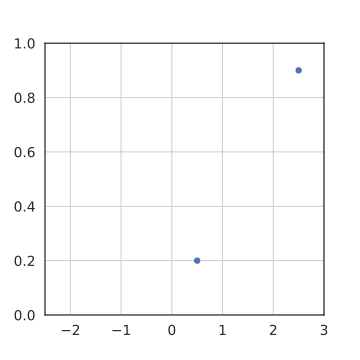
What does it mean to train the network?
x
y
(x_1,y_1)
(x_2,y_2)
f(x) = \frac{1}{1+e^{-(wx+b)}}
In other words
We hope to find a sigmoid function such that \((0.5, 0.2)\) and \((2.5, 0.9)\) lie on this sigmoid
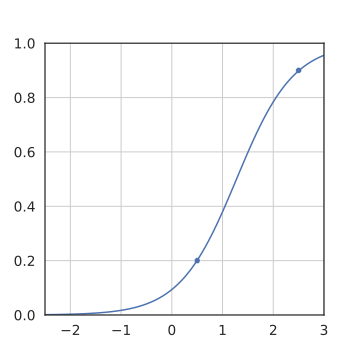
Suppose we train the network with \( (x, y) = (0.5, 0.2) \) and \((2.5, 0.9)\)
At the end of training we expect to find \(w^*\), \(b^*\) such that:
\( f(0.5) \rightarrow 0.2 \ \text{and} \ f(2.5) \rightarrow 0.9 \)
Let us see this in more detail ...
Can we find \( w^*,b^* \) manually?
Let us start with a Random Guess: \( w=3,b=-1\)
Clearly, it is not good, but how bad is it ?
Let us revisit \(\mathscr{L} (w, b) \) to see how bad it is ...
\mathscr{L(w,b)}= \frac{1}{N} \sum \limits_{i=1}^N (y_i-f(x_i))^2
= \frac{1}{2} * \big( (y_1-f(x_1))^2 + (y_2-f(x_2))^2 \big)
= \frac{1}{2} * \big( (0.9-f(2.5))^2 + (0.2-f(0.5))^2 \big)
= \frac{1}{2} * \big( (0.90-0.99)^2 + (0.20-0.62)^2 \big)
=0.099
We want \(\mathscr{L} (w, b) \) to be as close to zero as possible
Let us try some other values for \((w,b)\) by changing the sliders
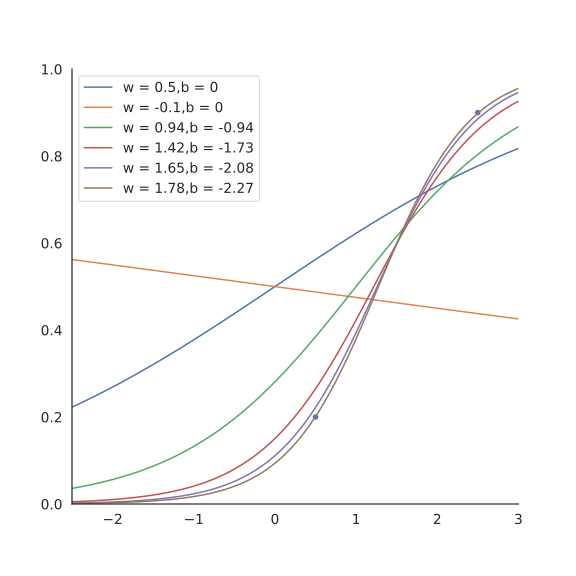
w |
b |
Loss |
|---|---|---|
| 0.50 | 0.00 | 0.0730 |
| -0.10 | 0.00 | 0.14 |
| 0.94 | -0.94 | 0.0214 |
| 1.42 | -1.73 | 0.0028 |
| 1.65 | -2.08 | 0.0003 |
| 1.78 | -2.27 | 0.0000 |
A few Snapshots
Let us Look for something better
than our "Guess work Algorithm"..
Since we have only 2 points and 2 parameters \((w, b)\) we can easily plot \(\mathscr{L}(w, b)\) for different values of \((w, b)\) and pick the one where \(\mathscr{L}(w, b)\) is minimum
Random Search on Error Surface
But of course, this becomes intractable once you have many more data points and many more parameters !!
Further, even here we have plotted the error surface only for a small range of \((w, b)\) [from (−6, +6) and not from \((-\infty, +\infty)\)]
Let us look at the geometric interpretation of our “guess work” algorithm in terms of this error surface
Play with the Search Space
w |
b |
Loss |
|---|---|---|
| 0.50 | 0.00 | 0.0730 |
| -0.10 | 0.00 | 0.14 |
| 0.94 | -0.94 | 0.0214 |
| 1.42 | -1.73 | 0.0028 |
| 1.65 | -2.08 | 0.0003 |
| 1.78 | -2.27 | 0.0000 |
Module 5.2: Learning Parameters :
Gradient Descent
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Goal
Find a better way of traversing the error surface so that we can reach the minimum value quickly without resorting to brute force search!
Vector of parameters, say,
randomly initialized
\( \theta = [w,b]\)
\( \Delta \theta = [\Delta w, \Delta b]\)
change in the value of
\(w,b\)
We moved in the
direction of \(\Delta \theta\)
Let us be a bit conservative:
move only by a small amount \(\eta \)
\(\theta_{new}=\theta+\eta \cdot \Delta \theta \)
Question: What is the right \(\Delta \theta\) to use ?
The answer comes from Taylor series
\theta
\Delta \theta
\color{red} \eta \cdot \Delta \theta
\theta_{new}
What is Taylor Series?
Taylor series is a way of approximating any continuously differentiable function \(\mathscr{L(w)}\) using polynomials of degree \(n\). The higher the degree the better the approximation!.
\(\mathscr{L}(w)=\mathscr{L}(w_0)+\frac{\mathscr{L'}(w_0)}{1!}(w-w_0)+\frac{\mathscr{L''}(w_0)}{2!}(w-w_0)^2+\frac{\mathscr{L'''}(w_0)}{3!}(w-w_0)^3+ \cdots\)
w
\mathscr{L}(w)
w_0
Linear Approximation (\( n=1 \))
\( \mathscr{L}(w)=\mathscr{L}(w_0)+ \frac{\mathscr{L'}(w_0)}{1!}(w-w_0) \)
Quadratic Approximation (\(n=2\))
\(\mathscr{L}(w)=\mathscr{L}(w_0)+\frac{\mathscr{L'}(w_0)}{1!}(w-w_0)+ \frac{\mathscr{L''}(w_0)}{2!}(w-w_0)^2 \)
\mathscr{L}(w_0)

Taylor Series Approximation
Try with different \( L(w) \) such as \(exp(w),sin(w),w^3 \cdots \) and see how closely Taylor series approximate the function at the point \(w = w_0\) and around its neighbour \(\epsilon \)
Approximating 2D function
For ease of notation, let \(\Delta \theta = u\) , then from Taylor series, we have,
\mathscr{L}(\theta+ \eta u) = \mathscr{L}(\theta)+\eta*u^T \nabla_{\theta}\mathscr{L}(\theta)+\frac{\eta^2}{2!}*u^T\nabla_{\theta}^2\mathscr{L}(\theta)u+
\frac{\eta^3}{3!} \cdots +\frac{\eta^4}{4!} \cdots
=\mathscr{L}(\theta)+\eta*u^T \nabla_{\theta}\mathscr{L}(\theta)
[ \( \eta\) is typically small, so \( \eta^2,\eta^3 \cdots\rightarrow 0\)]
Note that the move (\(\eta u\)) would be favorable only if
\mathscr{L}(\theta+\eta u)-\mathscr{L}(\theta) < 0
[i.e., if the new loss is less than the previous loss]
This implies,
u^T \nabla_{\theta}\mathscr{L}(\theta) < 0
But, what is the range of \( u^T \nabla_{\theta}\mathscr{L}(\theta) < 0 \)?
Let \( \beta \) be the angle between \( u^T \) and \( \nabla_{\theta} \mathscr{L}(\theta)\)
Let \( \beta \) be the angle between \( u^T \) and \( \nabla_{\theta} \mathcal{L}(\theta)\), then we know that
\(-1 \leq \cos(\beta) = \frac{ u^T \nabla_{\theta} \mathscr{L}(\theta)}{ ||u^T|| * ||\nabla_{\theta} \mathscr{L}(\theta)||} \leq 1 \)
Multiply throught \(k = ||u^T|| * ||\nabla_{\theta} \mathscr{L}(\theta)|| \)
\(-k \leq k*\cos(\beta) = u^T \nabla_{\theta} \mathscr{L}(\theta) \leq k \)
Thus \( \mathscr{L}(\theta+\eta u) - \mathscr{L}(\theta) = u^T \nabla_{\theta} \mathscr{L}(\theta) = k*\cos(\beta) \) is more negative when \(\cos(\beta)=-1\) (i.e., \(\beta\)=\(180^o\))
Gradient Descent Rule
The direction \(u\) that we intend to move in should be at 180° w.r.t. the gradient
In other words, move in a direction opposite to the gradient
Parameter Updation Rule
\( w_{t+1} = w_t - \eta \nabla w_t\)
\(b_{t+1} = b_t - \eta \nabla b_t \)
where, \( \nabla w_t = \frac{\partial \mathscr{L}(w,b)}{\partial w}\), at \(w=w_t,b=b_t \),
and, \( \nabla b_t = \frac{\partial \mathscr{L}(w,b)}{\partial b}\), at \(w=w_t,b=b_t \),
So we now have a more principled way of moving in the (\(w,b\)) plane than our “guess work” algorithm
Let us create an algorithm for this rule ...
To see this algorithm in practice let us first derive \( \nabla w \) and \( \nabla b\) for our toy neural network
max_iterations = 1000
w = random()
b = random()
while max_iterations:
  w = w - eta*dw
  b = b - eta*db
max_iterations -= 1Algorithm:gradient_descent()
\(t \leftarrow 0;\)
max_iterarions \(\leftarrow 1000\);
w,b \(\leftarrow\) initialize randomly
while \(t <\) max_iterations do
\(w_{t+1} \leftarrow w_t-\eta \nabla w_t\);
\(b_{t+1} \leftarrow b_t-\eta \nabla b_t\);
\( t \leftarrow t+1;\)
end
f(x) = \frac{1}{1+e^{-(wx+b)}}
1
x
\sigma
\hat{y}=f(x)
w
b
Let us assume there is only one point to fit
\mathscr{L}(w,b)=\frac{1}{2}*(f(x)-y)^2
\nabla w = \frac{\partial \mathscr{L}(w,b)}{\partial w} = \frac{\partial}{\partial w}[\frac{1}{2}*(f(x)-y)^2]
\nabla w = \frac{\partial}{\partial w}[\frac{1}{2}*(f(x)-y)^2]
= \frac{1}{2} [2*(f(x)-y) * \frac{\partial}{\partial w} (f(x)-y)]
=(f(x)-y) * \frac{\partial}{\partial w} (f(x))
=(f(x)-y) * \frac{\partial}{\partial w} (\frac{1}{1+e^{-(wx+b)}})
\frac{\partial}{\partial w} (\frac{1}{1+e^{-(wx+b)}})
= \frac{-1}{(1+e^{(wx+b)})^2} \frac{\partial}{\partial w} (e^{-(wx+b)})
= \frac{-1}{(1+e^{-(wx+b)})^2}* (e^{-(wx+b)})* \frac{\partial}{\partial w} (-(wx+b))
= \frac{-1}{(1+e^{-(wx+b)})}* \frac{e^{-(wx+b)}}{(1+e^{-(wx+b)})}* -x
= \frac{1}{(1+e^{-(wx+b)})}* \frac{e^{-(wx+b)}}{(1+e^{-(wx+b)})}* x
= f(x)*(1-f(x))* x
=(f(x)-y) * f(x)*(1-f(x))*x
f(x) = \frac{1}{1+e^{-(wx+b)}}
1
x
\sigma
\hat{y}=f(x)
w
b
(x_1,y_1)
(x_2,y_2)
\nabla w=(f(x)-y) * f(x)*(1-f(x))*x
So If we have only one point (\(x,y\)), we have,
For two points,
\nabla w=\sum \limits_{i=1}^{2}(f(x_i)-y_i) * f(x_i)*(1-f(x_i))*x_i
\nabla b=\sum \limits_{i=1}^{2}(f(x_i)-y_i) * f(x_i)*(1-f(x_i))
import numpy as np
X = [0.5,2.5]
Y = [0.2,0.9]

def f(x,w,b):
  return 1/(1+np.exp(-(w*x+b)))

def error(w,b):
  err = 0.0
  for x,y in zip(X,Y):
    fx = f(x,w,b)
    err += (fx-y)**2
  return 0.5*err

def grad_b(x,w,b,y):
  fx = f(x,w,b)
  return (fx-y)*fx*(1-fx)

def grad_w(x,w,b,y):
  fx = f(x,w,b)
  return (fx-y)*fx*(1-fx)*x

def do_gradient_descent():

  w,b,eta,max_epochs = -2,-2,1.0,1000

  for i in range(max_epochs):
    dw,db = 0,0
    for x,y in zip(X,Y):
      dw += grad_w(x,w,b,y)
      db += grad_b(x,w,b,y)

    w = w - eta*dw
    b = b - eta*db
Let us do_gradient_descent()
import numpy as np
X = [0.5,2.5]
Y = [0.2,0.9]

def f(x,w,b):
  return 1/(1+np.exp(-(w*x+b)))

def error(w,b):
  err = 0.0
  for x,y in zip(X,Y):
    fx = f(x,w,b)
    err += (fx-y)**2
  return 0.5*err

def grad_b(x,w,b,y):
  fx = f(x,w,b)
  return (fx-y)*fx*(1-fx)

def grad_w(x,w,b,y):
  fx = f(x,w,b)
  return (fx-y)*fx*(1-fx)*x

def do_gradient_descent():

  w,b,eta,max_epochs = -2,-2,1.0,1000

  for i in range(max_epochs):
    dw,db = 0,0
    for x,y in zip(X,Y):
      dw += grad_w(x,w,b,y)
      db += grad_b(x,w,b,y)

    w = w - eta*dw
    b = b - eta*db
import numpy as np
X = [0.5,2.5]
Y = [0.2,0.9]
def f(x,w,b):
return 1/(1+np.exp(-(w*x+b)))
def error(w,b):
err = 0.0
for x,y in zip(X,Y):
fx = f(x,w,b)
err += (fx-y)**2
return 0.5*err
def grad_b(x,w,b,y):
fx = f(x,w,b)
return (fx-y)*fx*(1-fx)
def grad_w(x,w,b,y):
fx = f(x,w,b)
return (fx-y)*fx*(1-fx)*x
def do_gradient_descent():
w,b,eta,max_epochs = -4,-4,1.0,1000
for i in range(max_epochs):
dw,db = 0,0
for x,y in zip(X,Y):
dw += grad_w(x,w,b,y)
db += grad_b(x,w,b,y)
w = w - eta*dw
b = b - eta*dbWhen the curve is steep the gradient \( \frac{\Delta y}{\Delta x}\) is large.
When the curve is gentle the gradient \( \frac{\Delta y}{\Delta x}\) is small.
Recall that our weight updates are proportional to the gradient \( w = w - \eta \nabla w \)
Hence in the areas where the curve is gentle the updates are small whereas in the areas where the curve is steep the updates are large
Drag the blue point to see how the slope changes.
Let’s see what happens when we start from a different point
Irrespective of where we start from once we hit a surface which has a gentle slope, the progress slows down
Try: \(w_{init}=-2,b_{init}=2\)
Try: \(w_{init}=-3,b_{init}=2\)
Set \(t_{max}=150\)
Module 5.3 : Contours
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Visualizing things in 3d can sometimes become a bit cumbersome
Can we do a 2d visualization of this traversal along the error surface
Yes, let’s take a look at something known as contours
Suppose I take horizontal slices of this error surface at regular intervals along the vertical axis
How would this look from the topview ?
A small distance between the contours indicates a steep slope along that direction
A large distance between the contours indicates a gentle slope along that direction
Gradient Descent
Module 5.4 : Momentum Based Gradient Descent
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
It is helpful to remember that the first iteration of any optimization algorithm starts with computing \(\nabla w_0\).
Some observations about gradient descent
It takes a lot of time to navigate regions having a gentle slope
This is because the gradient in these regions is very small
Can we do something better?
Yes, let’s take a look at Momentum based gradient descent
Update rule for momentum based gradient descent
u_t = \beta u_{t-1}+ \nabla w_t
w_{t+1} = w_t - \eta u_t
with, \( u_{-1}=0\), \(w_0 = rand()\) and \(0 \leq \beta < 1\)
In addition to the current update, also look at the history of updates.
Intuition
If I am repeatedly being asked to move in the same direction then I should probably gain some confidence and start taking bigger steps in that direction
Just as a ball gains momentum while rolling down a slope
u_0 = \nabla w_0, u_{-1} = 0
u_t = \beta u_{t-1}+ \nabla w_t
u_0 = \nabla w_0 \quad \because u_{-1}=0
u_1 = \beta u_0+\nabla w_1 = \beta (\nabla w_0)+\nabla w_1
u_2 = \beta u_1+\nabla w_2 = \beta (\beta \nabla w_0+\nabla w_1)+\nabla w_2=\beta^2 \nabla w_0+\beta \nabla w_1+\nabla w_2
u_t = \sum \limits_{\tau=0}^t \beta^{t-\tau} \nabla w_{\tau}
The exponentially weighted average of current and all past gradients.

def do_mgd(max_epochs):
    w,b,eta = -2,-2,1.0
    prev_uw,prev_ub,beta = 0,0,0.9

    for i in range(max_epochs):
        dw,db = 0,0
        for x,y in zip(X,Y):
            dw += grad_w(w,b,x,y)
            db += grad_b(w,b,x,y)

        uw = beta*prev_uw+eta*dw
        ub = beta*prev_ub+eta*db
        w = w - vw
        b = b - vb
        prev_uw = uw
        prev_ub = ub
Some Observations and questions
Even in the regions having gentle slopes, momentum based gradient descent is able to take large steps because the momentum carries it along
Is moving fast always good? Would there be a situation where momentum would cause us to run pass our goal?
Let us change our input data so that we end up with a different error surface and then see what happens ...
In this case, the error is high on either side of the minima valley
Could momentum be detrimental in such cases... let’s see....


Momentum based gradient descent oscillates in and out of the minima valley as the momentum carries it out of the valley
Takes a lot of u-turns before finally converging
\(w_0=-2, b_0=-4, \eta=1 \)
Despite these u-turns it still converges faster than vanilla gradient descent
After 50 iterations (25 iterations per second) momentum-based method has reached an error of 0.00001 whereas vanilla gradient descent is still stuck at an error of 0.16
Module 5.5 : Nesterov Accelerated Gradient Descent
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Questions
Can we do something to reduce these oscillations ?
Yes, let’s look at Nesterov accelerated gradient
Intuition
Look before you leap
Update rule for NAG
u_t = \beta u_{t-1}+ \nabla (w_t - \beta u_{t-1})
w_{t+1} = w_t - \eta u_t
with, \( u_{-1}=0\) and \(0 \leq \beta < 1\)
Recall that \( u_t = \beta u_{t-1}+\nabla w_t\)
So, we know that we are going to move by at least by \( \beta u_{t-1}\) and then a bit more by \(\nabla w_t\)
Why not make use of this to look ahead instead of relying only on the current \(\nabla w_t\)
def do_nag(max_epochs):
    w,b,eta = -2,-2,1.0
    prev_vw,prev_vb,beta = 0,0,0.9

    for i in range(max_epochs):
        dw,db = 0,0
        # do partial updates
        v_w = beta*prev_vw
        v_b = beta*prev_vb
        for x,y in zip(X,Y):
            # Look ahead
            dw += grad_w(w-v_w,b-v_b,x,y)
            db += grad_b(w-v_w,b-v_b,x,y)
        vw = beta*prev_vw+eta*dw
        vb = beta*prev_vb+eta*db
        w = w - vw
        b = b - vb
        prev_vw = vw
        prev_vb = vb
Observations about NAG
Looking ahead helps NAG in correcting its course quicker than momentum-based gradient descent.
Hence the oscillations are smaller and the chances of escaping the minima valley are also smaller.
Module 5.6 : Stochastic And Mini-Batch Gradient Descent
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Let’s digress a bit and talk about the stochastic version of these algorithms...
import numpy as np
X = [0.5,2.5]
Y = [0.2,0.9]


def do_gradient_descent():

  w,b,eta,max_epochs = -2,-2,1.0,1000

  for i in range(max_epochs):
    dw,db = 0,0
    for x,y in zip(X,Y):
      dw += grad_w(x,w,b,y)
      db += grad_b(x,w,b,y)

    w = w - eta*dw
    b = b - eta*db
Notice that the algorithm goes over the entire data once before updating the parameters
Why?
Because this is the true gradient of the loss as derived earlier (sum of the gradients of the losses corresponding to each data point)
No approximation.
Hence, theoretical guarantees hold (in other words each step guarantees that the loss will decrease)
What’s the flipside?
Imagine we have a million points in the training data.
To make 1 update to \(w, b\) the algorithm makes a million calculations. Obviously very slow!!
Can we do something better?.
Yes, let’s look at stochastic gradient descent
def do_stochastic_gradient_descent():

  w,b,eta,max_epochs = -2,-2,1.0,1000

  for i in range(max_epochs):
    dw,db = 0,0
    for x,y in zip(X,Y):
      dw += grad_w(x,w,b,y)
      db += grad_b(x,w,b,y)
      w = w - eta*dw
      b = b - eta*db
def do_gradient_descent():
w,b,eta,max_epochs = -2,-2,1.0,1000
for i in range(max_epochs):
dw,db = 0,0
for x,y in zip(X,Y):
dw += grad_w(x,w,b,y)
db += grad_b(x,w,b,y)
w = w - eta*dw
b = b - eta*dbNotice that the algorithm updates the parameters for every single data point
Now if we have a million data points we will make a million updates in each epoch (1 epoch = 1 pass over the data; 1 step = 1 update)
What is the flipside ?
Stochastic because we are estimating the total gradient based on a single data point.
It is an approximate (rather stochastic) gradient
Almost like tossing a coin only once and estimating P(heads).
No guarantee that each step will decrease the loss
Let’s see this algorithm in action when we have a few data points
We see many oscillations. Why ?

Because we are making greedy decisions.
Each point is trying to push the parameters in a direction most favorable to it (without being aware of how this affects other points)
A parameter update which is locally favorable to one point may harm other points (it is almost as if the data points are competing with each other)
Can we reduce the oscillations by improving our stochastic estimates of the gradient? (currently estimated from just 1 data point at a time)
Yes, let’s look at mini-batch gradient descent
def do_stochastic_gradient_descent():

  w,b,eta,max_epochs = -2,-2,1.0,500

  for i in range(max_epochs):
    dw,db = 0,0
    for x,y in zip(X,Y):
      dw += grad_w(x,w,b,y)
      db += grad_b(x,w,b,y)
      w = w - eta*dw
      b = b - eta*db
def do_minibatch_stochastic_gradient_descent():
w,b,eta,max_epochs = -2,-2,1.0,500
mini_batch_size = 25
for i in range(max_epochs):
dw,db,num_points_seen = 0
for x,y in zip(X,Y):
dw += grad_w(x,w,b,y)
db += grad_b(x,w,b,y)
num_points_seen += 1
if num_points_seen%minibatch_size == 0:
w = w - eta*dw
b = b - eta*db
dw,db = 0,0Notice that the algorithm updates the parameters after it sees mini_batch_size number of data points
The stochastic estimates are now slightly better
Let’s see this algorithm in action when we have \(k = 25\)
With a batch size of \(k=25\) the oscillations have reduced to a good extent.

With a batch size of \(k=25\) the oscillations have reduced to a good extent. Why ?
Because we now have slightly better estimates of the gradient [analogy: we are now tossing the coin \(k=25\) times to estimate P(heads)]
The higher the value of \(k\) the more accurate are the estimates
Of course, there are still oscillations and they will always be there as long as we are using an approximate gradient as opposed to the true gradient
Some things to remember..
1 epoch = one pass over the entire data
| Algorithm | # of steps in 1 epoch |
|---|---|
| Vanilla (Batch) Gradient Descent | |
| Stochastic Gradient Descent | |
| Mini Batch Gradient Descent |
\frac{N}{B}
N
1
1 step = one update of the parameters
\(N\) = Number of data points
\(B\) = Mini Batch size
Similarly, we can have stochastic versions of Momentum based gradient descent and Nesterov accelerated based gradient descent
\(\beta =0.5\)
SGD with Momentum
SGD-NAG-Momentum
\(\beta=0.85\)

While the stochastic versions of both Momentum [green] and NAG [blue] exhibit oscillations the relative advantage of NAG over Momentum still holds (i.e., NAG takes relatively shorter u-turns)
Further both of them are faster than stochastic gradient descent (after 500 steps, stochastic gradient descent [black] still exhibits a very high error whereas NAG and Momentum are close to convergence)
And, of course, you can also have the mini batch version of Momentum and NAG...I leave that as an exercise

Module 5.7 : Tips for Adjusting learning Rate and Momentum
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Before moving on to advanced optimization algorithms let us revisit the problem of learning rate in gradient descent
One could argue that we could have solved the problem of navigating gentle slopes by setting the learning rate high (i.e., blow up the small gradient by multiplying it with a large \(\eta\))
Let us see what happens if we set the learning rate to 10
On the regions which have a steep slope, the already large gradient blows up further
It would be good to have a learning rate which could adjust to the gradient ...
we will see a few such algorithms soon..
Tips for initial learning rate
Tune learning rate [Try different values on a log scale: 0.0001, 0.001, 0.01, 0.1. 1.0]
Run a few epochs with each of these and figure out a learning rate which works best
Now do a finer search around this value [for example, if the best learning rate was 0.1 then now try some values around it: 0.05, 0.2, 0.3]
Disclaimer: these are just heuristics ... no clear winner strategy
Tips for annealing learning rate
Step Decay:
Halve the learning rate after every 5 epochs or
Halve the learning rate after an epoch if the validation error is more than what it was at the end of the previous epoch

Tips for annealing learning rate
Exponential Decay:
\(\eta=\eta_0^{-kt}\) where \(\eta_0\) and \(k\) are
hyperparameters and \(t\) is a step number

Tips for annealing learning rate
1/t Decay:
\(\eta=\frac{\eta_0}{1+kt}\) where \(\eta_0\) and \(k\) are
hyperparameters and \(t\) is a step number

Tips for momentum
The following schedule was suggested by Sutskever et. al., 2013
\( \beta_t = min(1-2^{-1-\log_2(\lfloor \frac{t}{250} \rfloor+1)},\beta_{max}) \)
where, \(\beta_{max}\) is choosen from \(\{0.999,0.995,0.99,0.9,0\}\)
Module 5.8: Line Search
Mitesh M. Khapra
AI4Bharat, Department of Computer Science and Engineering, IIT Madras
Just one last thing before we move on to some other algorithms ...
def do_line_search_gradient_descent(max_epochs):
    w,b,etas = -2,-2,[0.1,0.5,1,2,10]

    for i in range(max_epochs):

        dw,db = 0,0
        for x,y in zip(X,Y):
            dw += grad_w(w,b,x,y)
            db += grad_b(w,b,x,y)

        min_error = 10000  # some large value
        for eta in etas:
          temp_w = w - eta * dw
          temp_b = b - eta * db
          if error(temp_w,temp_b) < min_error:
            best_w = temp_w
            best_b = temp_b
            min_error = error(best_w,best_b)
        w = best_w
        b = best_b
In practice, often a line search is done to find a relatively better value of \(\eta\)
Update \(w\) using different values of \(\eta\)
Now retain that updated value of \(w\) which gives the lowest loss
Essentially at each step, we are trying to use the best \(\eta\) value from the available choices
What’s the flipside?
def do_line_search_gradient_descent(max_epochs):
    w,b,etas = -2,-2,[0.1,0.5,1,2,10]

    for i in range(max_epochs):

        dw,db = 0,0
        for x,y in zip(X,Y):
            dw += grad_w(w,b,x,y)
            db += grad_b(w,b,x,y)

        min_error = 10000  # some large value
        for eta in etas:
          temp_w = w - eta * dw
          temp_b = b - eta * db
          if error(temp_w,temp_b) < min_error:
            best_w = temp_w
            best_b = temp_b
            min_error = error(best_w,best_b)
        w = best_w
        b = best_b
A line search can be done to find a relatively better value of \(\eta\)
Update \(w\) using different values of \(\eta\)
Now retain that updated value of \(w\) which gives the lowest loss
Essentially at each step, we are trying to use the best \(\eta\) value from the available choices
What’s the flipside? We are doing many more computations in each step
Blue: Gradient descent with fixed learning rate \(\eta=1\)
Black: Gradient descent with line search
Let us see line search in action
Convergence is faster than vanilla gradient descent
We see some oscillations, but note that these oscillations are different from what we see in momentum and NAG
CS6910: Lecture 5
By Arun Prakash